Gemini 4 Neon: 61 on AA Index, $3 / $15
Official benchmarks, Artificial Analysis cost and time per task across thinking levels, and monthly bill estimates.
Four releases in seven weeks split Gemini 4 across four distinct points on the speed, intelligence, and price curve. Here is how Carbon, Neon, Hydrogen, and Argon compare on benchmarks, per-task cost, and daily coding workloads.
Over seven weeks in late 2026, Google shipped four Gemini 4 models: Argon, Carbon, Hydrogen, and Neon. Instead of a simple small-medium-large ladder, each element targets a different point on the capability, latency, and cost curve.
All four share a 1-million-token context window and native multimodal input (text, image, video, audio, PDF), yet their benchmark ceilings, output speeds, thinking levels, and API bills differ sharply.
The short take: Use Gemini 4 Neon as your everyday default for complex coding and agents (high scores 60 on the AA Intelligence Index at less than half the time and cost of Carbon). Route high-frequency edits and subagents to Hydrogen (~140 tok/s at half Neon's price). Carbon and Argon keep their $2 / $10 intro rate only through November 30; once they double to $4 / $20 on December 1, save Carbon for the hardest long-horizon problems.
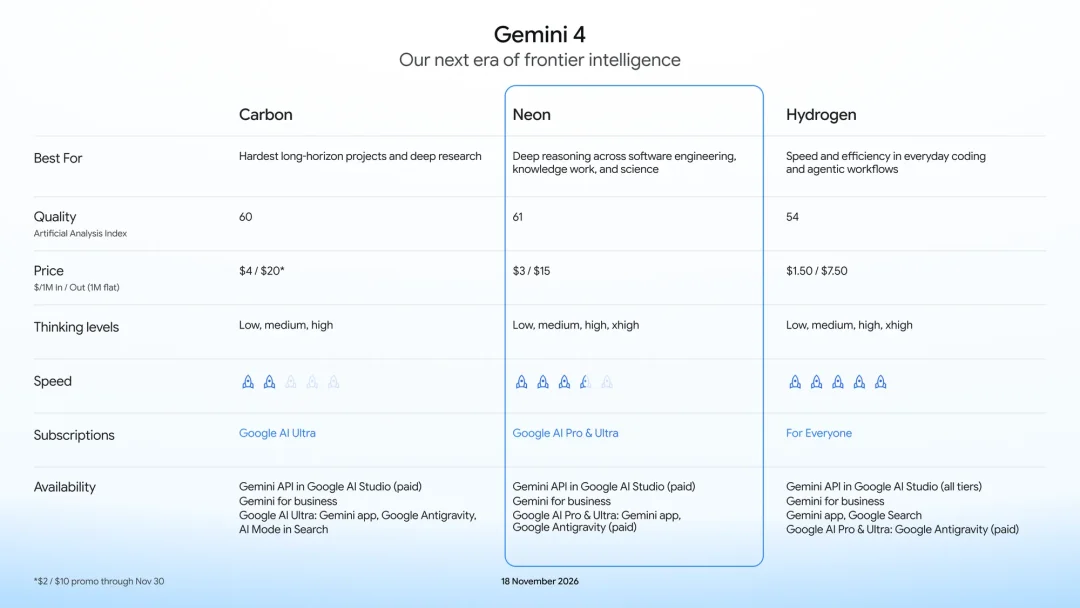
Putting Argon back into the same table shows how the full four-model lineup fits together:
| Spec / Metric | Carbon | Neon | Hydrogen | Argon |
|---|---|---|---|---|
| Primary focus | Hardest long-horizon tasks & deep research | Complex coding, knowledge work & science | Fast, low-cost daily coding & subagents | Early baseline & general automation |
| AA Intelligence Index (peak) | 60 (high) | 61 (xhigh) / 60 (high default) | 54 (xhigh) / 51 (high) | 50 (high) / 48 (medium) |
| Output speed (approx.) | 57 tok/s | 110 tok/s | 140 tok/s | Moderate-slow |
| Thinking levels | low, medium, high | low, medium, high (default), xhigh | low, medium, high, xhigh | low, medium (default), high |
| Context window | 1M tokens | 1M tokens | 1M tokens | 1M tokens |
| API input / output (per 1M) | $4 / $20 ($2 / $10 through Nov 30) | $3 / $15 | $1.50 / $7.50 | $4 / $20 ($2 / $10 through Nov 30) |
| Cached input (per 1M) | $0.20 ($0.10 through Nov 30) | $0.15 | $0.075 | $0.20 ($0.10 through Nov 30) |
| CodingPass minimum plan | Plus | Go | Go | Go |
One channel detail to note: Google removed Argon from the Gemini consumer app's model selector (which now lists Auto, Hydrogen, Neon, and Carbon), though gemini-4-argon remains active on the API pricing page and on CodingPass.
As for Gemini 4 Krypton, which has circulated in SVG and video demos on X, it is still an unreleased test checkpoint with no official API pricing or full benchmark suite, so it is left out of production recommendations here.
The four models separate along three axes: terminal coding reliability, 1M-token recall, and how many thinking tokens each task burns.
| Evaluation | Carbon | Neon | Hydrogen | Argon |
|---|---|---|---|---|
| AA Intelligence Index | 60 | 60 (high) / 61 (xhigh) | 51 (high) / 54 (xhigh) | 50 (high) |
| Terminal-Bench 4.0 / 4.1 | 65.2% (4.0) | 65.2% (4.1) / 61.62% (Vals 4.0) | 54.04% (4.0) | ~57.2% (4.0) |
| GraphWalks (256k–1M) | 96.2% | 95.2% | — | 84.2% |
| Agent Arena | +16.2% (#2) | 1336 Elo (#2) | — | +11.0% (#7) |
| AA cost per task (high / max) | $7.76 (Dec pricing) | $3.74 (high) / $6.44 (xhigh) | $3.16 (xhigh) | Above median |
| AA time per task | 34.2 min (25.6 min early) | 14.8 min (high) / 22.6 min (xhigh) | 14.9 min (xhigh) | Slower |
Carbon is built for long-horizon reasoning where exploring multiple hypotheses matters more than speed. It tops GraphWalks (256k–1M) at 96.2% and ranked #1 in Agent Arena on mid-session course correction when users push back or change requirements.
The trade-off is heavy token consumption and latency. Across the full Artificial Analysis Intelligence Index suite, Carbon emitted 205M tokens versus a 72.8M peer median, running around 57 tok/s and averaging 25.6 to 34.2 minutes per task.
Adapted from Carbon, Neon hits the same 60-point AA Intelligence Index score at its default high level while cutting time per task from 34.2 minutes to 14.8 minutes and cost from $7.76 (post-December pricing) to $3.74.
On several domain benchmarks, Neon beats Carbon outright:
Hydrogen is also adapted from Carbon, tuned for ~140 tok/s output at half of Neon's per-token price ($1.50 / $7.50). When pushed to xhigh, Hydrogen reaches 54 on the AA Intelligence Index—outscoring the earlier Argon (50).
In Google Antigravity's Orchestrator mode, pairing Carbon or Neon as the planner with Hydrogen for file edits, dependency bumps, and test runs achieves near-Carbon success rates on Terminal-Bench while finishing roughly 19% faster and using about 24% less quota.
Argon launched first with strong long-context recall (84.2% on GraphWalks) and native multimodal streaming. Once Hydrogen and Neon arrived, Argon lost its niche: its Intelligence Index (50) trails Hydrogen (high 51 / xhigh 54), and after the December 1 increase to $4 / $20, it costs more per token than Neon ($3 / $15). Unless an existing pipeline is tuned around Argon's medium default, new workloads have little reason to pick it.
Neon and Hydrogen expose four thinking levels (low, medium, high, xhigh), while Carbon and Argon offer three (low, medium, high). Defaults differ too: Argon defaults to medium, whereas Carbon and Neon default to high. Migrating from Argon to Neon without setting reasoning_effort: "medium" will noticeably increase output token counts.
Assuming 20,000 input tokens per request (50% implicit cache hit at 5% of input rate) and 2,000 output tokens, monthly API bills scale as follows:
| Model | Per request | 10K req | 100K req | 1M req |
|---|---|---|---|---|
| Gemini 4 Hydrogen | $0.031 | $308 | $3,075 | $30,750 |
| Gemini 4 Neon | $0.062 | $615 | $6,150 | $61,500 |
| Carbon / Argon (through Nov 30) | $0.041 | $410 | $4,100 | $41,000 |
| Carbon / Argon (from Dec 1) | $0.082 | $820 | $8,200 | $82,000 |
Four caveats matter when reading the numbers above:
mini-SWE harness, Neon drops to 12.8%—just 1.2 points ahead of GPT-6.2 Sol (11.6%).xhigh has steep diminishing returns: Stepping from high to xhigh adds 1 Intelligence Index point (60 to 61) while raising per-task cost by 72% ($3.74 to $6.44), adding nearly 8 minutes, and regressing on GDP.pdf document reading (33.4% down to 28.0%).high default generates more thinking tokens on well-guided prompts.CodingPass meters all four Gemini 4 models at official Google API rates. Hydrogen, Neon, and Argon start on Go; Carbon starts on Plus:
| Model | Min plan | Go | Plus | Pro |
|---|---|---|---|---|
| Gemini 4 Hydrogen | Go | 305M | 1.0B | 2.5B |
| Gemini 4 Neon | Go | 205M | 508M | 1.3B |
| Gemini 4 Argon | Go | 205M | 761M | 1.9B |
| Gemini 4 Carbon | Plus | — | 761M | 1.9B |
Switch models per request on a single key and set reasoning_effort to match the job:
curl https://codingpass.ai/v1/chat/completions \ -H "Authorization: Bearer $CODINGPASS_API_KEY" \ -H "Content-Type: application/json" \ -d '{ "model": "gemini-4-neon", "reasoning_effort": "medium", "messages": [{"role": "user", "content": "Review the diff in src/billing/ for race conditions"}] }'| Workload | Recommended | Rationale and trade-off |
|---|---|---|
| Routine edits, unit tests, high-volume subagents | Hydrogen (medium / high) | ~140 tok/s at half of Neon's price; avoids overthinking simple prompts |
| Multi-file refactors, debugging, primary coding agent | Neon (high default) | Matches Carbon's 60 AA score in less than half the time and cost |
| Financial, legal, and spreadsheet analysis | Neon (high) | #1 on Vals Finance & Legal; avoid xhigh where document reading drops |
| Stuck architectural bugs, 1M-token repo audits | Carbon (high) or Neon (xhigh) | 96.2% on GraphWalks; expect 30+ minute runs and higher token spend |
| Existing Argon workflows | Migrate to Neon (medium) | Argon is slower and pricier after Dec 1; medium keeps output tokens in check |
For most teams, Neon (medium or high) is the right default, with Hydrogen handling fast subagent loops and Carbon reserved for problems that stall Neon twice in a row.
high) is the best primary coding model, ranking #1 on the AA Coding Agent Index while running over twice as fast as Carbon. Pair it with Hydrogen for fast subagent edits and test runs.reasoning_effort explicitly to medium. Argon defaults to medium, whereas Neon defaults to high, which generates noticeably more thinking tokens if left at the default.Go, Plus and Pro meter at official API prices. No surprise charges, cancel anytime.